Reward Is Not a Universal Interface for Generative Reinforcement Learning
TL;DR
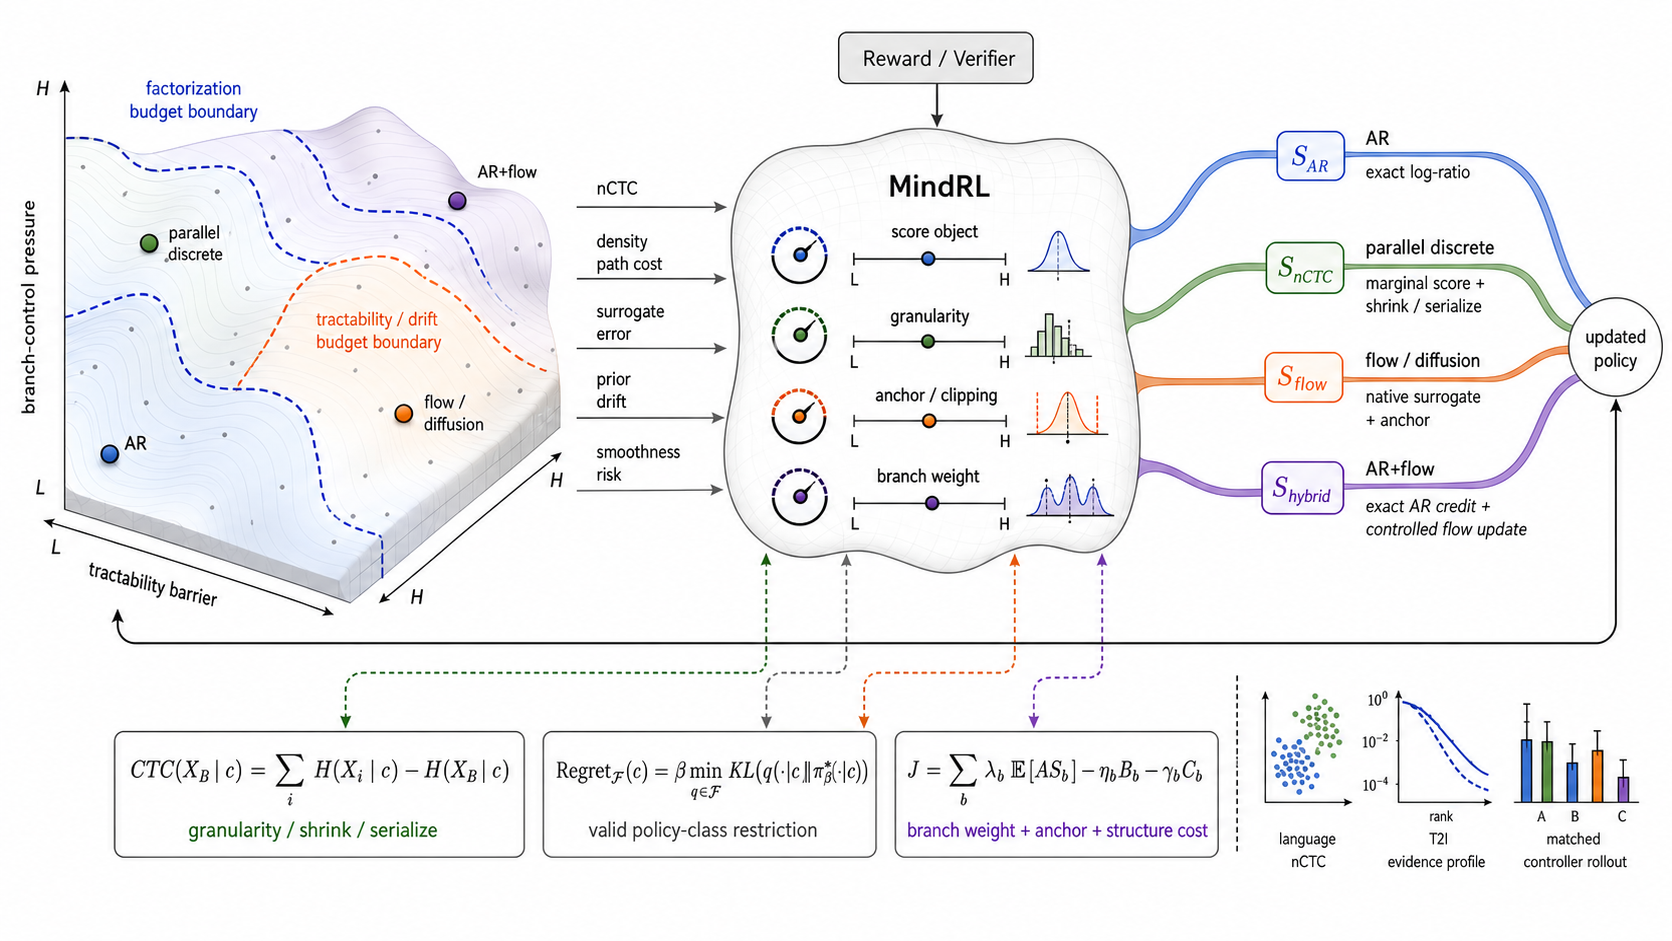
MindRL translates a shared reward into updates suited to autoregressive, parallel discrete, flow, and hybrid policies, with explicit controls on update reliability.MindRL 将共同奖励转化为适合自回归、并行离散、Flow 及混合策略的更新,并显式控制更新的可靠性。
Citation
@inproceedings{huang2026reward,
  title = {Reward Is Not a Universal Interface for Generative Reinforcement Learning},
  author = {Huang, Victor Shea-Jay and Chu, Poodar and Li, Hongsheng},
  booktitle = {Advances in Neural Information Processing Systems},
  year = {2026},
  note = {Accepted},
  url = {https://openreview.net/forum?id=gbYg6VGblU}
}