Publications

Reinforcement learning, multimodal generation, LLMs & agents, and physical AI.强化学习、多模态生成、LLMs & Agents 与 Physical AI。

2-minute research overview两分钟研究介绍 Open video ↗打开视频 ↗
arXiv2026Preprint

SWE-Shift: Evaluating Coding Agents in Evolving Workspaces

Victor Shea-Jay Huang, Rongqing Li, Zhangyue Yin, Kelong Mao, Yaqi Zhao, Xinyuan Wang, Yao Yin, Lirui Luo, Renrui Zhang, Hongsheng Li

TL;DR A benchmark for coding agents facing mid-execution changes. Across 120 scenarios and 12 change families, all 17 evaluated systems have lower success after the workspace changes.评测 Coding Agent 在执行过程中应对变化的能力。覆盖 120 个场景、12 类变化,17 个受测系统在工作环境变化后的成功率均下降。

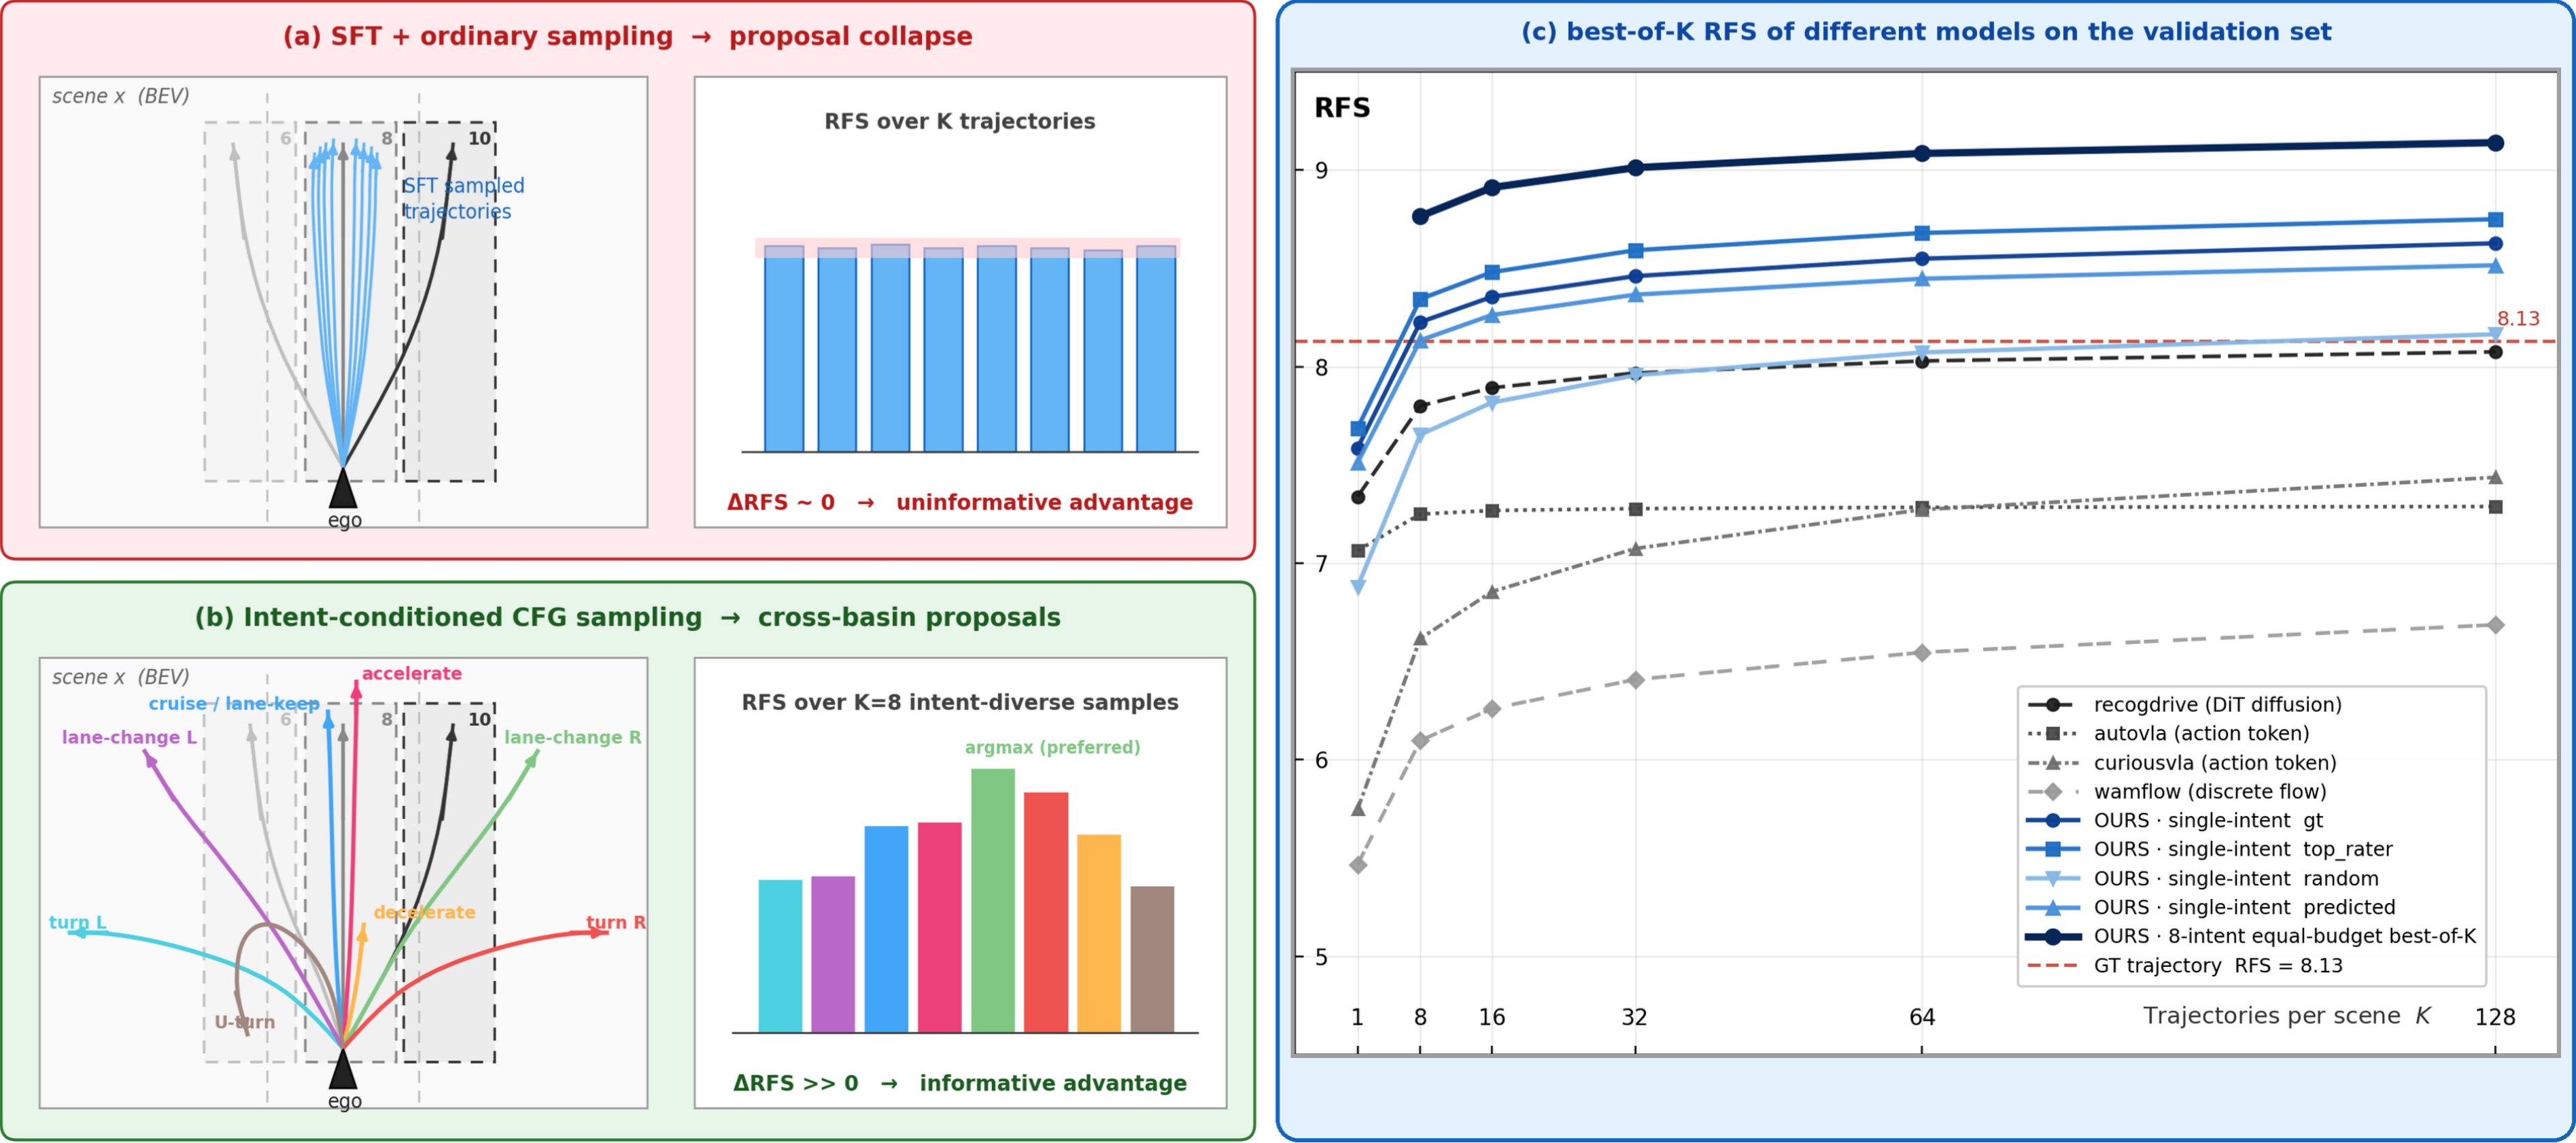
DIAL contrasts collapsed trajectory samples with diverse intent-conditioned proposals and plots their best-of-K preference scores.
arXiv2026Preprint

Driving Intents Amplify Planning-Oriented Reinforcement Learning

Hengtong Lu (equal contribution), Victor Shea-Jay Huang (equal contribution), Chengmin Yang, Pengfei Jing, Jifeng Dai, Yan Xie, Benjin Zhu (equal contribution)

TL;DR Intent-conditioned proposals and multi-intent GRPO expand and preserve diverse driving maneuvers for preference-based reinforcement learning.通过意图条件采样与多意图 GRPO,扩展并保留多样驾驶行为,为基于偏好的强化学习提供更丰富的候选轨迹。

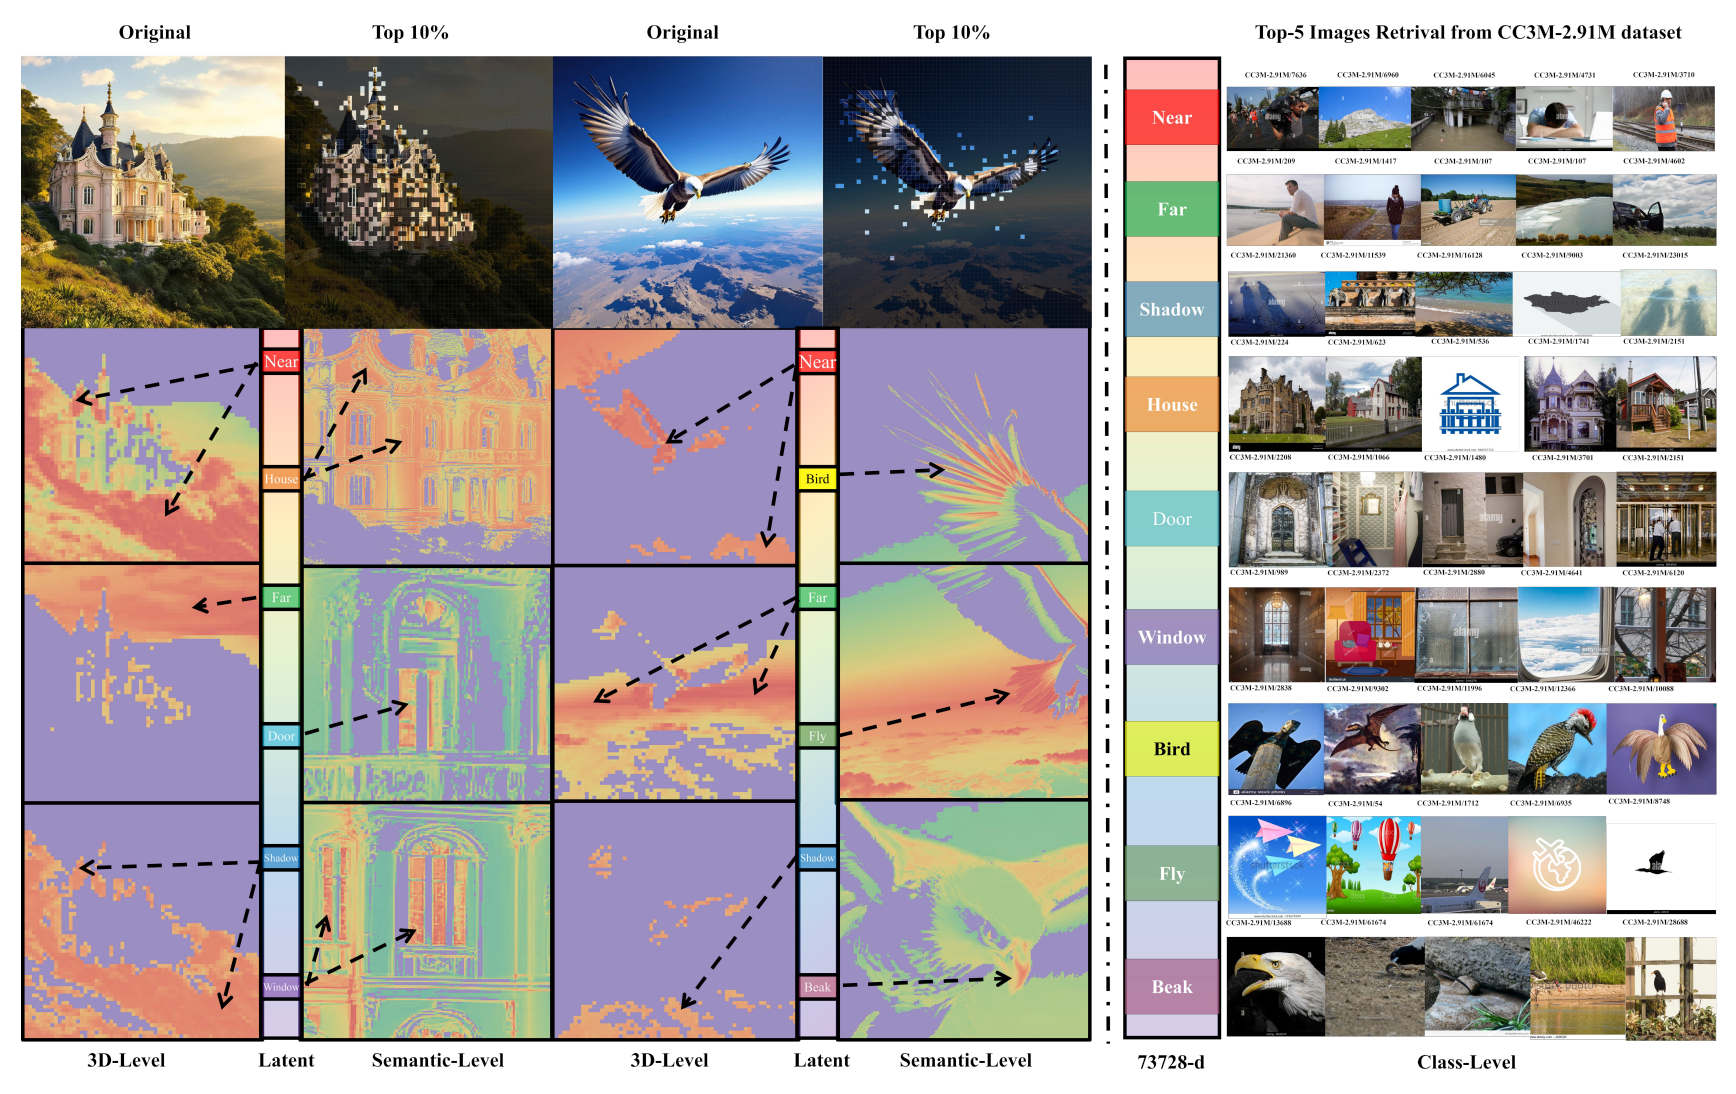
TIDE visualizes spatial, semantic, and class-level sparse features for generated house and bird images.
AAAI 2026Published

TIDE: Temporal-Aware Sparse Autoencoders for Interpretable Diffusion Transformers in Image Generation

Victor Shea-Jay Huang (equal contribution), Le Zhuo (equal contribution), Yi Xin, Zhaokai Wang, Fu-Yun Wang, Yuchi Wang, Renrui Zhang, Peng Gao, Hongsheng Li

TL;DR Temporal-aware sparse autoencoders reveal hierarchical concepts across diffusion timesteps, making diffusion transformers easier to interpret and control.用时间感知的稀疏自编码器提取扩散各时间步中的层次化概念,理解并控制 Diffusion Transformer 的生成过程。

BlackDAN's framework combines black-box model responses, judge models, and NSGA-II multi-objective optimization.
ICML 2025 · New In MLWorkshop poster

BlackDAN: A Black-Box Multi-Objective Approach for Effective and Contextual Jailbreaking of Large Language Models

Xinyuan Wang (equal contribution), Victor Shea-Jay Huang (equal contribution), Renmiao Chen, Hao Wang, Chengwei Pan, Lei Sha, Minlie Huang

TL;DR A black-box evaluation framework uses multi-objective optimization to study jailbreak success, contextual relevance, and detectability together.以多目标优化联合考察越狱成功率、上下文相关性与可检测性,构建黑盒大语言模型安全评测框架。

The 3MAD dataset spans medical imaging modalities and question types used to evaluate medical multimodal model safety.
AAAI 2025Published

Medical MLLM Is Vulnerable: Cross-Modality Jailbreak and Mismatched Attacks on Medical Multimodal Large Language Models

Xijie Huang (equal contribution), Xinyuan Wang (equal contribution), Hantao Zhang (equal contribution), Yinghao Zhu (equal contribution), Jiawen Xi, Jingkun An, Hao Wang, Hao Liang, Chengwei Pan

TL;DR The 3MAD dataset and MCM optimization expose cross-modal safety weaknesses in medical multimodal language models.通过 3MAD 数据集与 MCM 优化,揭示医疗多模态大语言模型在图文错配及跨模态攻击下的安全薄弱点。